Repository navigation
Temp-worker task dispatch failure is archived as done and leaves the worker live #663
Description

What happened?
After a temp worker has started, an exception while sending its objective is logged but treated as a successful spawn request. On current public main (f44b986a), processSpawnRequest() registers the worker in liveWorkers, then catches an error from hive.send() and continues to archiveRequest(filePath, '.done').
For example, when the atomic rename into the worker's inbox throws EACCES, the worker has no task, the request is under .done, and the new PTY and broker capability remain live. Resubmitting the request under the same filename is rejected as worker "worker-demo" already running. No dispatch-failure notice reaches god through the existing failure path.
try {
  // ... build the task brief ...
  hive.send(/* objective to the new worker */);
} catch (e) {
  console.error('[worker] dispatch send failed:', e);
}
// Execution still reaches this after failure:
archiveRequest(filePath, '.done');
Expected behavior
An exception during initial task dispatch should fail the request, inform god (including any Slack reply coordinates), and stop/clean up the newly spawned worker through the existing worker teardown. Isolated work must retain its existing preservation checks. If stopping the process fails, the request should still be reported as failed while the process remains tracked for operator attention.
An exception can occur after partial delivery, so the failure notice should advise inspecting partial delivery/work before a manual retry; no automatic resend is requested.
Steps to reproduce and evidence
I reproduced this against current public main with deterministic filesystem fault injection, without spending a model call:
- Set up a temporary hive with god and submit a valid
spawn-requests/demo.jsoncontaining an objective and existing cwd. - Model successful CLI launch, then inject
EACCESinto the final atomic rename toagents/worker-demo/inbox/<message>.json. - Execute the production
processSpawnRequest()and the realHiveManager.send(). - Observe the unbriefed worker still live, the request archived to
.done, and no rejection notice. Submit the corrected request again and it cannot reuse the live id.
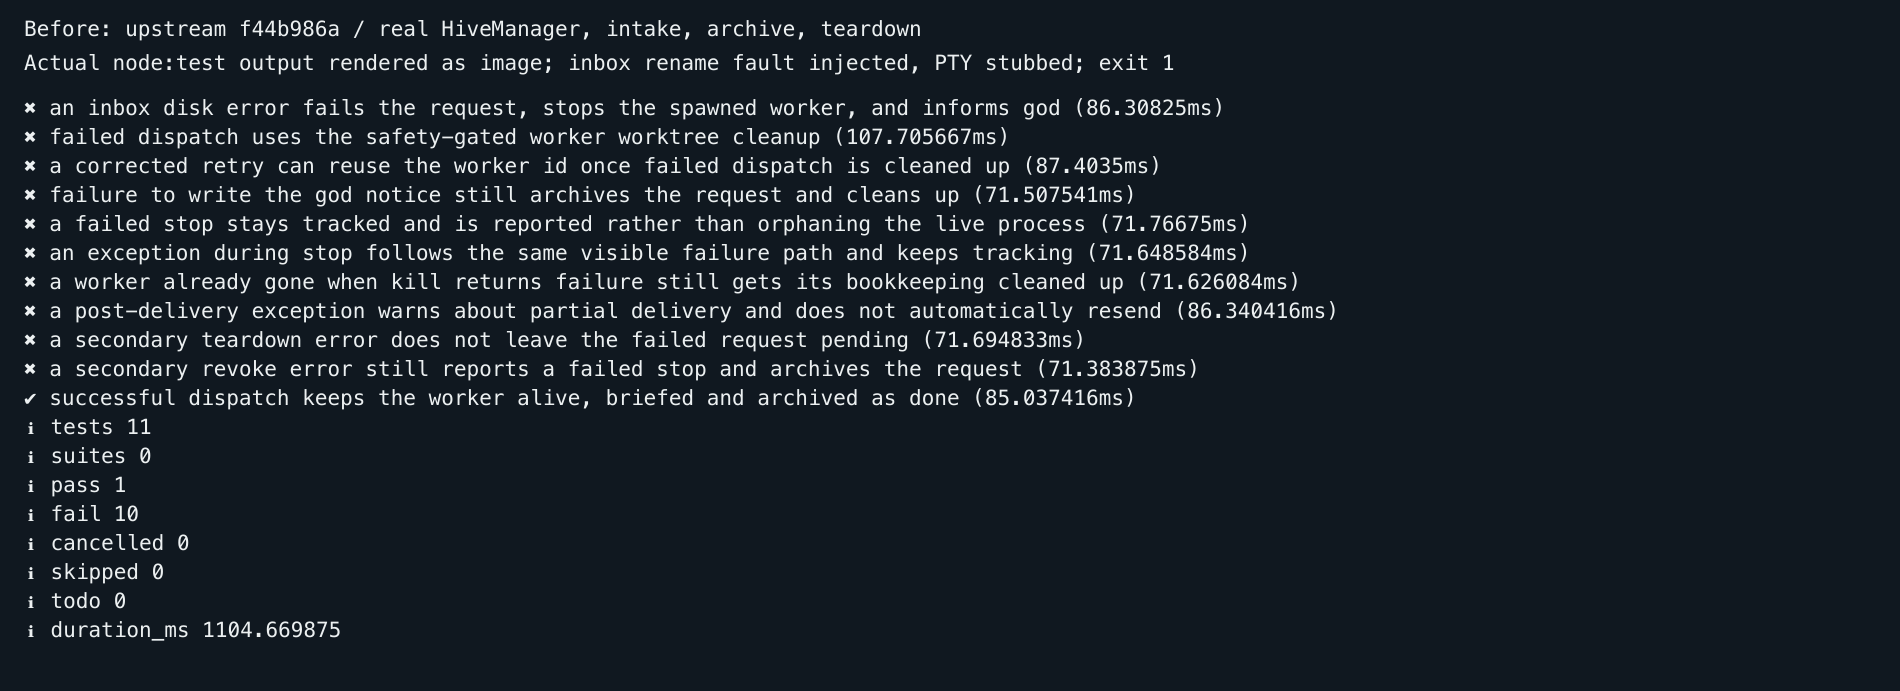
The executable regression tests use real temp files, HiveManager, and the production intake/archive/notification/teardown functions. PTY launch/stop and external services are stubbed; the worktree finalizer is a spy verifying that teardown delegates to the existing preservation gate. This is a source-level reproduction, not a live CLI or packaged-application smoke test.
The same final suite against unchanged upstream main reports 1 pass / 10 failures. The image renders the actual node:test output:
Environment and scope
- Public source revision:
f44b986a4dd6490179a60a55db0a32e2f498f9ea(package.json version0.4.6). - Reproduction: macOS 26.4.1, Apple Silicon, Node.js v24.13.0.
- CLI engine version: not applicable; actual CLI process calls are stubbed in this fault-injection test.
- Searched issues and PRs for dispatch/worker-brief/inbox-write failures; no duplicate found.
- Distinct from Spawn request whose strings hold control characters starts a temp with a garbled brief, and the corrected copy is then refused as "already running" (v0.5.2) #648: that concerns corrupted input before launch; this concerns an exception after successful launch. It also differs from hive: outbox 信件无法投递时被静默隔离 —— 发送方与 orchestrator 都收不到任何信号 #604's outbox quarantine/reporting behavior.
Activity